RESEARCH / VISUAL BRIEF01 / 06
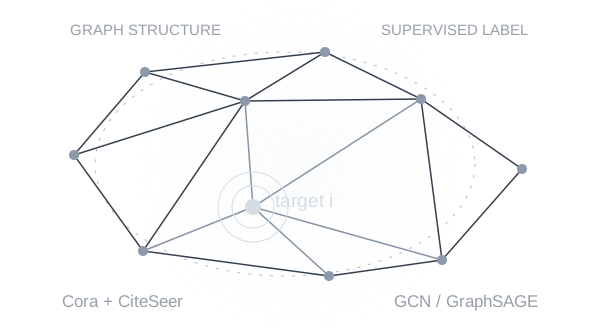
Learning, or memorising?
Measure how much a node and its neighbourhood depend on one training label.
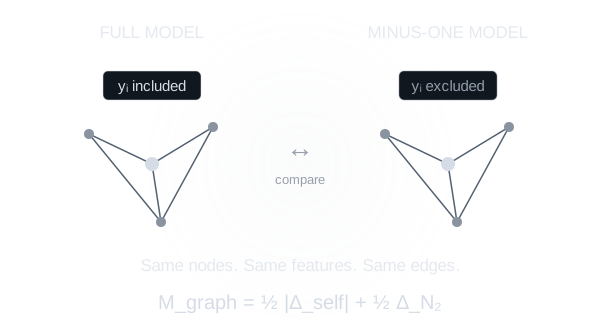
One label. Two models.
Retrain with and without the target label. Keep the node, its features, and the graph unchanged.
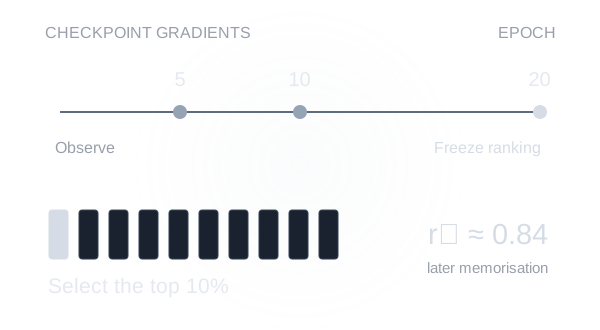
Spot risk at epoch 20.
Gradient norm ranks later memorisation (rₛ ≈ 0.84); simpler signals are competitive.
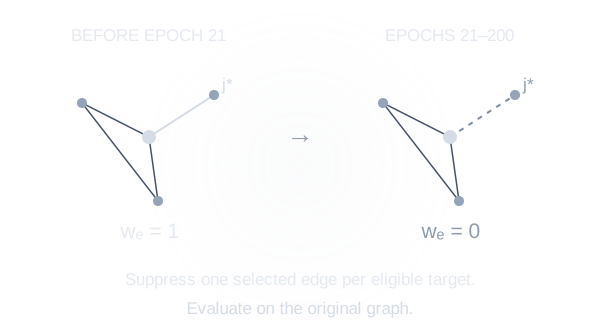
Change the training path.
Suppress the most-negative eligible edge during epochs 21–200. Evaluate on the original graph.
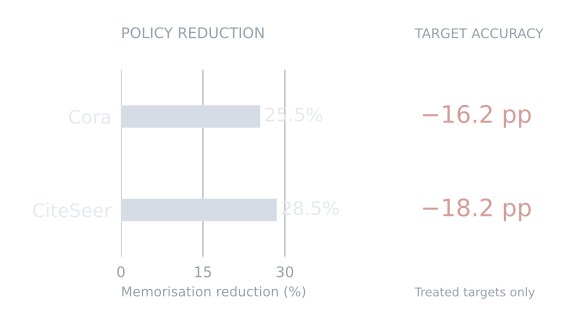
Less dependence. A real cost.
Memorisation falls, but treated-node accuracy drops. Main GCN setting: 70% training labels, three splits.
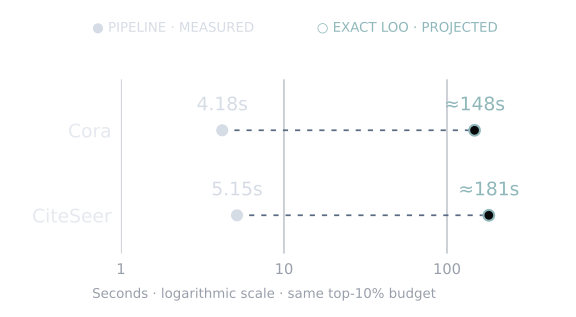
≈35× lower projected cost.
Measured pipeline versus projected exact leave-one-out cost, at the same top-10% target budget.
Machine learning / MSc dissertation
Understanding what
graph networks memorise.
Detecting memorisation during training and investigating targeted interventions in graph neural networks.